Nowadays I make a habit of writing up how to use particular tools or techniques for anything which might be useful to reference later. Many techniques I worked on before starting this practice are now lost to me, locked away in proprietary source code at some previous employer.
This post concerns data binding from XML schemas in C++, generating classes rather than manipulating the underlying XML. As its written for Future Me, it might not be so interesting to those who are not Future Me.
Consider the simple XML schema shown below. I aspire to be the Evil Overlord, and am working on the HR system to keep track of my innumerable minions.
<?xml version="1.0" encoding="ISO-8859-1" ?>
<xs:schema xmlns:xs="http://www.w3.org/2001/XMLSchema">

<xs:element name="minion">
  <xs:complexType>
    <xs:sequence>
      <xs:element name="name" type="xs:string"/>
      <xs:element name="rank" type="xs:string"/>
      <xs:element name="serial" type="xs:positiveInteger"/>
    </xs:sequence>
    <xs:attribute name="loyalty" type="xs:float" use="required"/>
  </xs:complexType>
</xs:element>

</xs:schema>
It would be possible to parse documents created from this schema manually, using something like libexpat or Xerces. Unfortunately as the schema becomes large, the likelihood of mistakes in this manual process becomes overwhelming.
I chose instead to work with CodeSynthesis XSD to generate classes from the schema, based mainly on the Free/Libre Open Source Software Exception in their license. This project will eventually be released under an Apache-style license, and all other data binding solutions I found for C++ were either GPL or a commercial license.
Parsing from XML
The generated code provides a number of function prototypes to parse XML from various sources, including iostreams.
std::istringstream agent_smith( "<?xml version=\"1.0\" encoding=\"UTF-8\" standalone=\"no\" ?>" "<minion xmlns:xsi=\"http://www.w3.org/2001/XMLSchema-instance\" " "xsi:noNamespaceSchemaLocation=\"schema.xsd\" loyalty=\"0.2\">" "<name>Agent Smith</name>" "<rank>Member of Minion Staff</rank>" "<serial>2</serial>" "</minion>"); std::auto_ptrm(NULL); try { m = minion_(agent_smith); } catch (const xml_schema::exception& e) { std::cerr << e << std::endl; return; }
The minion object now contains data members with proper C++ types for each XML node and attribute.
std::cout << "Name: " << m->name() << std::endl
          << "Loyalty: " << m->loyalty() << std::endl
          << "Rank: " << m->rank() << std::endl
          << "Serial number: " << m->serial() << std::endl;
Serialization to XML
Methods to serialize an object to XML are not generated by default, the --generate-serialization flag has to be passed to xsdcxx. This emits another series of minion_ methods, which take output arguments.
int main() {
  minion m("Salacious Crumb", "Senior Lackey", 1, 0.9);
  minion_(std::cout, m);
}
This sends the XML to stdout.
<?xml version="1.0" encoding="UTF-8" standalone="no" ?>
<minion loyalty="0.9">
  <name>Salacious Crumb</name>
  <rank>Senior Lackey</rank>
  <serial>1</serial>
</minion>
Codesynthesis relies on Xerces-C++ to provide the lower layer XML handling, so all of the functionality of that library is also available to the application.
Thats enough for now. See you later, Future Me.

 In a typical datacenter, the servers sit behind a load balancer. The simplest such equipment distributes sessions without modifying the packets, but the market demands
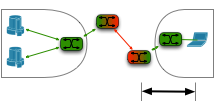 High speed wide area networks are expensive. If a one-time purchase of a magic box at each end can reduce the monthly cost of the connection between them, then there is an economic benefit to buying the magic box.
 Organizations set up HTTP proxies to enforce security policies, cache content, and a host of other reasons.

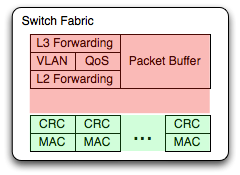 Ethernet frames carry a CRC32 to ensure data integrity. It is often assumed that this CRC is carried all the way across the network, but in reality there are cases where the switch fabric modifies the frame and calculates a new CRC at egress. For example:


 We can reduce the number of lookup cycles by trading off an increased number of entries in the table. The hardware will be designed to only search for a limited number of prefix lengths (the specific masks would be programmable). Software expands all entries of prefix lengths between those the hardware will lookup. In the sample diagram the hardware can search with a /24 mask, and it will find the /22 route because it has been expanded into four /24 entries. Any incoming IP address in the range which should match the /22 will find one of the four entries in the table.
 This technique also has to deal with overlapping routes. When a more specific /23 route is added, it should overwrite two of the entries from the less specific /22 route. Addition and deletion of entries in the hash table is complex in this scheme, particularly because it has to be done while packets continue to flow through the device. Nonetheless its always preferable to tolerate complexity in software than to make the hardware handle it. A bug in production software can be fixed. A bug in production hardware turns into a software bug to work around it.
 Hash complexity: In software hash implementations we trade off the time to compute the hash function versus the benefit we get from better distribution. Hardware hash functions are far less sensitive to the complexity of the computation. The concern is only about the amount of chip area the function takes up, and even very complex hash functions are an insignificant fraction of modern chips. ASICs generally use very complex hash functions with good distribution properties. CRCs of various polynomials are common, and MD2 is also used.

 Many hash functions: The downside of large buckets is that they tend to be poorly occupied: an entire bucket must be allocated to hold one entry. If a smaller amount of very fast random access memory is available, like SRAM, large buckets are not a good match. Single entry buckets will be used instead.
 Therefore we look for ways to handle even ruinous collisions. A clever fallback option is to include a very small CAM as an adjunct to a hash-and-match design. A CAM on the order of a dozen entries can be synthesized in logic using register bits and gates. This is very inefficient compared with custom CAM silicon, but with such a small number of entries it is tolerable. If no match is found in the hash table, the ASIC will consult its on-chip CAM before giving up. Now you can take the unlikely case of collision in every candidate hash location, and handle twelve of them. Whatever the probability of such catastrophic collision, make it an order of magnitude less likely to cause a problem and it becomes less likely to keep an ASIC designer up at night.

