Monday, August 9, 2010

Mispsleled Words in Code

I ran into an interesting variation on the brain being able to recnogzie mispsleled wrods so long as the first and last letters are correct.

char *filename = "XXXXXX"; 
mkstemp(filename); 

One of the resulting runs produced:

-rwx------ 2 dgentry eng 4096 Jul 8 10:41 ufseuL

Why yes, it was useful. Thank you for your efforts, computer.

Wednesday, August 4, 2010

node.js from 30,000 feet

I attended a tech talk last week on node.js by Ryah Dahl. The video of the talk is up on YouTube.


Node.js Overall Structure

V8+libev+libeio+libcares at the bottom, node bindings in the middle, top layer node.js standard library in JavaScriptThe JavaScript implementation in node.js is Google's V8. As mentioned in an earlier article, V8 compiles the source JavaScript directly to machine code the first time it is executed. There is no intermediate bytecode format and no JS interpreter. In addition to V8, node.js relies on libev for its event loop, libeio for asynchronous I/O, and c-ares for asynchronous DNS support. Like everything else in the known universe, it relies on OpenSSL for cryptography and SSL/TLS support.

A standard library in JavaScript is supplied. This provides access to the underlying C++ implementation, and also has helpful bits like a URL parser and a REPL shell for easy experimentation. One thing it does not provide is the DOM. Node.js is not a browser, there is no HTML document to interact with.


Node.js Implementation

Entry points to the C++ code appear as a JavaScript variable named process. For example, here is an excerpt from dns.js:

var dns = process.binding('cares');

'cares' refers to the c-ares DNS support library. The dns variable allows JavaScript code to make calls to c-areas.

// Easy DNS A/AAAA look up
exports.lookup = function (domain, callback) {

Notice the signature of the function: input arguments and a callback when finished. There are never blocking operations in node, everything which might not complete immediately is a callback.

  var addressType = dns.isIP(domain);
  if (addressType) {
    process.nextTick(function () {
      callback(null, domain, addressType);
    });

dns.isIP() calls into C++ code, which makes a series of inet_pton(AF_INET*) calls to figure out if the argument is a valid numeric IP address. I've omitted the C++ code here, we dive into a more interesting example below.

  } else {
    if (/\w\.local\.?$/.test(domain) ) {
      // ANNOYING: In the case of mDNS domains use NSS in the thread pool.
      // I wish c-ares had better support.
      process.binding('net').getaddrinfo(domain, 4, function (err, domains4) {
        callback(err, domains4[0], 4);
      });

Node.js has two ways to implement support routines in C++. If the C++ code is structured to be asynchronous with a callback, it can be launched from the main thread using libev. Node.js makes heavy use of async I/O for this reason. Blocking C++ calls are handled by a pool of worker threads, which send an event to the main when their operation completes. In this code snippet the 'local' domain is handled by the thread pool as a special case, because c-ares doesn't handle mDNS.

We'll come back to the thread pool code path later, after examining the common case.

    } else {
      channel.getHostByName(domain, dns.AF_INET, function (err, domains4) {
        if (domains4 && domains4.length) {
          callback(null, domains4[0], 4);
        } else {
          channel.getHostByName(domain, dns.AF_INET6, function (err, domains6) {
            if (domains6 && domains6.length) {
              callback(null, domains6[0], 6);
            } else {
              callback(err, []);
            }
          });
        }
      });
      ... etc ...

"channel" is a JavaScript variable which links to a context in the c-ares library. The JS code to create channel is omitted for brevity. Now we'll peel back one layer to look at the C++ implementation.

Handle Channel::GetHostByName(const Arguments& args) {
  HandleScope scope;
  Channel *c = ObjectWrap::Unwrap(args.Holder());
  assert(c);

  if (!args[0]->IsString()) {
    return ThrowException(Exception::Error(
          String::New("First argument must be a name")));
  }

  if (!args[1]->IsInt32()) {
    return ThrowException(Exception::Error(
          String::New("Second argument must be a family")));
  }

  if (!args[2]->IsFunction()) {
    return ThrowException(Exception::Error(
          String::New("Third argument must be a callback")));
  }

  int family = args[1]->Int32Value();
  if (family != AF_INET6 && family != AF_INET) {
    return ThrowException(Exception::Error(
          String::New("Unsupported address family")));
  }

Argument unwrapping and validity checks when traversing the interface from one programming language are always tedious. You can never predict when someone will copy the channel.getHostByName invocation out of the standard library and mess with it, and you'd like the framework to do something sane no matter what they do.

  String::Utf8Value name(args[0]->ToString());

  ares_gethostbyname(c->channel, *name, family, HostByNameCb, cb_persist(args[2]));

  return Undefined();
}

Thats it. ares_gethostbyname() is in the C-ARES library, which we won't delve into here. HostByNameCb is the C++ callback function when resolution is done. HostByNameCb injects an event to the JavaScript code, to call the callback function passed in to the original call.

The JavaScript has an alternate code path for mDNS requests, using the getaddrinfo() method on process.binding('net'). Most of that code path consists of the same sort of argument unwrapping and checking as GetHostByName, which we will omit. The mDNS code path uses a blocking DNS request, serviced by the thread pool. The code to send work to the pool and arrange a callback later is pleasingly simple:

  eio_custom(Resolve, EIO_PRI_DEFAULT, AfterResolve, rreq);

Resolve is the function the worker thread is supposed to call. AfterResolve is the callback function in the main loop which the worker thread should trigger when done.


Final Thoughts

Node.js makes it easy to develop high performance applications by not offering APIs which would drastically lower performance. Everything is a callback, there are no blocking calls in the API (except for initialization calls such as module loading). Where the underlying C++ implementation is also based on callbacks, this is straightforward. Where the underlying C++ code would block, the implementation becomes a somewhat more difficult exercise in thread management.

The JavaScript API in node.js "feels" very much like JavaScript. I believe a main factor making this possible is the relatively small number of entry points required from the JavaScript down into the C++ code: sockets, DNS resolution, the http parsing library, etc. It was feasible for each interface to be lovingly crafted by hand, baking JavaScriptiness into the API.

Attempting this technique for software like GUIs, where the number of C/C++ APIs to bind to is enormous, would likely require a more automated linkage between JavaScript and C++. This is the world of things like SWIG to generate interfaces or libffi to make direct calls. SWIG and libffiare extremely useful in their niches, but definitely have the feel of a foreign intruder in the host language. I don't know that a node.js for GUIs would be as pleasant a thing to look upon, but we need a way to do so. Software needs to advance without having to continually reinvent and reimplement what has come before, and without requiring drastic amounts of manual effort.

Monday, August 2, 2010

Zeus SCM

Closeup of face from statue of ZeusThe last few years have seen much innovation in source code management systems. Personally I find these systems to be needlessly complex, and have long wished for a simpler option. Therefore it is with great pride that I announce a new source code management system: Zeus. Its name comes from a particular event in Greek mythology where Pallas Athena bursts forth, fully grown, from the forehead of Zeus. The guiding principle of Zeus is that source code should appear in its final form, and thus dispenses with such outmoded concepts as file versions and history. Source files simply spring forth from the repository, in all their glory.

Zeus relies on a single environment variable for all of its settings: ${REPO}. This is the central source repository where all files will reside. Zeus supports both local and remote filesystems such as NFS. The Zeus command structure is designed to leverage a developer's familiarity with existing shell commands. For example, checking code out from the repository is deliberately very similar to a copy command:

zeus cp ${REPO}/file.cc client/

Other available Zeus commands include, but are not limited to:

  • zeus ls ${REPO} : list files in the repository
  • zeus ls -l ${REPO} : detailed information about files in the repository
  • zeus echo "note" >> ${REPO}/notes.txt : maintain a feature request list in the repository
  • zeus cat ${REPO}/file.cc : print file.cc to the console, without checking it out

Another great thing about Zeus is its simple, straightforward implementation. Any developer can understand its workings, and implement changes to meet their needs.

#!/bin/sh

# Zeus source code management system
# Copyright 8/2010, Denton Gentry

# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.

# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.

# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.

exec $*

I hope you enjoy using Zeus as much as I do. Many thanks to Mark Essel for his contribution of ideas.

Wednesday, July 28, 2010

Exploring libjit

Continuing investigation into JIT compilation for virtual machines, today we will delve into some of the plumbing. libjit is a library for implementing JIT compilers in a platform independent way. A virtual machine calls functions within libjit to emit abstract, low level operations such as arithmetic computation or branches. libjit will handle translation to the native opcodes of the platform on which it is running. x86 and ARM are currently supported, with other CPU architectures falling back to a slower interpreted path. libjit was created for DotGNU portable.NET by Rhys Weatherley, then the lead developer of the project. It is now used in the Mono project, an open source effort to implement the .NET CLR.

To investigate libjit we'll turn to the Official Subroutine for Programming Language Evaluation on the Internet, Fibonacci numbers. We'll start with an iterative C implementation:

unsigned long long fib (unsigned int n) {
  if (n <= 2) return 1;
  unsigned long long a = 1, b = 1, c;
  do {
    c = a + b;
    b = a;
    a = c;
    n--;
  } while (n > 2);
  return c;
}

libjit is designed to be driven from an Abstract Syntax Tree description of an algorithm. By descending through the AST outputting JIT operations at each node, you can construct native instructions for that algorithm. Had we written fib() in an interpreted language, we'd start with the AST within the interpreter. For the purposes of this example I've skipped the AST, manually constructing a fibonacci number routine by translating each line of C source code into JIT calls. The code is below, for your edification and bemusement.

jit_function_t create_fib_jit (jit_context_t *context) {
  jit_type_t param;
  jit_type_t signature;
  jit_function_t function;
  jit_value_t n, a, b, c;
  jit_value_t constant, compare, n_minus_1, a_plus_b;
  jit_label_t label1 = jit_label_undefined;
  jit_label_t label2 = jit_label_undefined;

  jit_init();
  *context = jit_context_create();
  jit_context_build_start(*context);

  /* Build the function signature, fib(unsigned int) */
  param = jit_type_uint;
  signature = jit_type_create_signature(jit_abi_cdecl, jit_type_ulong,
                                        &param, 1, 1);
  function = jit_function_create(*context, signature);

  /* Begin emitting instructions */

  /* "if (n <= 2)" */
  n = jit_value_create(function, jit_type_uint);
  n = jit_value_get_param(function, 0);
  constant = jit_value_create_nint_constant(function, jit_type_uint, 2);
  compare = jit_insn_le(function, n, constant);
  jit_insn_branch_if_not(function, compare, &label1);

  /* "return 1;" */
  constant = jit_value_create_nint_constant(function, jit_type_ulong, 1);
  jit_insn_return(function, constant);

  /* "if (n <= 2)" else branches here */
  jit_insn_label(function, &label1);

  /* "unsigned long long a = 1, b = 1, c;" */
  constant = jit_value_create_nint_constant(function, jit_type_ulong, 1);
  a = jit_value_create(function, jit_type_ulong);
  jit_insn_store(function, a, constant);
  b = jit_value_create(function, jit_type_ulong);
  jit_insn_store(function, b, constant);
  c = jit_value_create(function, jit_type_ulong);

  /* "do {" */
  jit_insn_label(function, &label2);

  /* "c = a + b;
   *  b = a;
   *  a = c;" */
  a_plus_b = jit_insn_add(function, a, b);
  jit_insn_store(function, c, a_plus_b);
  jit_insn_store(function, b, a);
  jit_insn_store(function, a, c);

  /* "n--;" */
  constant = jit_value_create_nint_constant(function, jit_type_uint, 1);
  n_minus_1 = jit_insn_sub(function, n, constant);
  jit_insn_store(function, n, n_minus_1);

  /* "} while (n > 2);" */
  constant = jit_value_create_nint_constant(function, jit_type_uint, 2);
  compare = jit_insn_gt(function, n, constant);
  jit_insn_branch_if(function, compare, &label2);

  /* "return c;" */
  jit_insn_return(function, c);

  if (jit_function_compile(function) == 0) {
    printf("compilation error occurred\n");
  }
  jit_context_build_end(*context);
  return function;
}

libjit compiles this function to native opcodes. Running on x86, the resulting assembly looks a great deal like the series of jit_insn_* calls which generated it.

   push   %rbp
   mov    %rsp,%rbp
   sub    $0x20,%rsp
   mov    %r12,(%rsp)
   mov    %r13,0x8(%rsp)
   mov    %r14,0x10(%rsp)
   mov    %r15,0x18(%rsp)
   mov    %rdi,%r15
   cmp    $0x2,%edi
   ja     A
   mov    $0x1,%eax
   jmpq   C
A: mov    $0x1,%r14d
   mov    $0x1,%r13d
B: mov    %r14,%r12
   add    %r13,%r12
   mov    %r14,%r13
   mov    %r12,%r14
   dec    %r15d
   cmp    $0x2,%r15d
   ja     B
   mov    %r12,%rax
C: mov    (%rsp),%r12
   mov    0x8(%rsp),%r13
   mov    0x10(%rsp),%r14
   mov    0x18(%rsp),%r15
   mov    %rbp,%rsp
   pop    %rbp
   retq   

How does it perform compared to the C version? I ran each in a loop of 1,000,000 iterations computing fib(75). The function was run once outside the timing loop, to avoid cache miss effects. The C code was compiled with -O0 and -O2, which made a huge difference in the results. Invoking gcc -O3 resulted in slower code due to overly aggressive loop unrolling. Similarly, libjit can set an optimization level via jit_function_set_optimization_level(), though it made no measurable difference in the results.

C -O0: 367.2 nsecs/iteration
libjit: 344.8 nsecs/iteration
C -O2: 110.1 nsecs/iteration

In this example libjit achieved the speed of a naive C compilation. This makes sense, it is the result of a naive programmer translating C code.

The point of this series of articles is the promise, not necessarily the current reality. The great promise of JIT compilation as compared to static is the ability to make optimizations based on profiling, even specializing routines for specific input values. The routine can sanity check its inputs, and escape back into the interpreter if the input does not match expectations. This would be of great benefit in large code bases, where we frequently have variables which are essentially constant. For example in a web application the language setting is a variable, though any individual user essentially never changes their language setting in the middle of a session. We'll explore this idea more in the future.

Monday, July 26, 2010

Victorian Arduino

You might think this is a painting of an espresso machine, but that is incorrect. Its actually an early Victorian prototype of the Arduino, and an espresso machine is just one of the projects it can be used for.

As this first Arduino shipped before the invention of semiconductors, it is steam powered.


Saturday, July 24, 2010

WWMD?

When Apple announced its A4 ARM CPU, I speculated about what would be in it. This speculation turned out to be completely wrong, but it was fun to write and engendered some good conversations about the possibilities. Now that Microsoft has signed an architecture license for ARM, I'm going to do it again. This article is complete speculation, and therefore rubbish. I am reliant on the same public sources of information as everyone else. Here we go.


What Will Microsoft Do?

Many companies license core designs from ARM, building them into chips with peripherals to add functionality. The various levels of ARM license offer both synthesized gate-level netlists and encrypted synthesizable RTL. An architectural license is much more extensive, allowing development of entirely new implementations of the ARM instruction set. Only the architectural license conveys the unencrypted, modifiable source code for the processor design. According to news reports, three other companies currently have an architectural license: Qualcomm, Marvell Semiconductor and Infineon Technologies. Qualcomm develops the Snapdragon, a line of ARM CPUs with integrated DSP and various mobile-related features. Marvell now owns the license originally used by DEC for development of the StrongARM, and under which Intel later produced the XScale. Infineon entered into the licensing agreement in late 2009, and will focus on security applications. Infineon is one of the few companies which embeds DRAM cells into the same die as the logic, and presumably will use this capability for HD SIM cards and other applications.

More notable than the list of architecture licensees is the list of companies which do not license the architecture. Samsung, which produces vast numbers of ARM CPUs, is content to work with ARM cores. Apple uses a Cortex A8 core in the A4, and does not have an architectural license either. Neither do TI, Cirrus Logic, or Atmel. Most companies use ARM core designs, and spend their efforts on the logic surrounding the CPU.

XCU from XBox360-SI tend to agree with The Register's take on it: Microsoft's ARM license is all about the XBox. Windows Mobile phones and the Zune use ARM, but there is little justification in producing their own chip for these markets. The XBox is the one hardware product which Microsoft produces itself, which can gain a competitive advantage via a unique CPU design, and which sells in large enough volume to be worth it. Microsoft already employs a great deal of custom silicon from suppliers in the product, such as the XCGPU used in the XBox 360-S. This chip combines the main PowerPC CPU and the ATI GPU onto a single die, with a second DRAM die incorporated into the package.


Its the Architecture, Stupid

So what might Microsoft do? I'll speculate that they won't design their own entirely new pipeline, the return on investment seems slim compared to other things they could spend time on. Its more likely they'd start from an existing ARM core and begin making changes. Microsoft will certainly integrate a powerful GPU onto the processor die, not doing so would be a step backwards from the existing XBox 360-S. I'll speculate they will tightly couple the GPU, allowing very low latency access to it as an ARM coprocessor in addition to the more straightforward memory mapped device. This is not unique: some of the on-chip XScale functional units can be accessed both as coprocessors for low latency and as memory mapped registers to get to the complete functionality of the unit. Having very low latency access to the GPU would allow efficient offloading of even small chunks of processing to GPU threads.

Yet even ARM coprocessors can be designed without needing an architectural license. TI implements its DaVinci DSP as a coprocessor, and Cirrus Logic had its own Maverick Crunch FPU. Neither company is an architectural licensee. So why would Microsoft feel it needs one?

One possibility is to let the GPU directly access the ARM processor cache and registers. This would allow GPU offloading to work almost exactly like a function call, putting arguments into registers or onto the stack with a coprocessor instruction to dispatch the GPU. When the GPU finishes, the ARM returns from the function call. For operations where the GPU is dramatically better suited, the ARM CPU would spend less time stalled than it would take to compute the result itself. If the ARM CPU supported hardware threads, it could switch to a different register file and run some other task while the GPU is crunching.

Part of the success of the XBox is due to its straightforward programming model compared to the Sony PS3. XBox has a fast SMP CPU paired with a GPU, where PS3 has an unruly gaggle of Cell processors to be managed explicitly. XBox cannot rely on the individual cores getting faster, as single core performance has leveled off due to power dissipation constraints. XBox has to make it easy for game developers to take advantage of more cores. Tightly coupling the GPU threads so they can function more like one big SMP system is one avenue to do this.


Wrapping up

I'll say it again: I made this all up. I have no insight into the specifics of Microsoft's intentions, just speculation. In the unlikely event that anyone reads this, don't copy it into Wikipedia as though it were verified information.

Monday, July 19, 2010

Fibre Channel over Token Ring

Token Ring connectorMonday morning posts on this site are normally jokes, funny observations, and amusing bits of fluff. Today I have to tip my hat to something far more elaborate: Fibre Channel over Token Ring. I can only stand in awe of the work of true masters.
The Fibre Channel link technology is lossless, with extensive flow control and data integrity mechanisms to ensure all data is delivered. Running Fibre Channel over Ethernet is saddled with significant complexity. Had Token Ring won the LAN battle instead of Ethernet, running Fibre Channel over it would be simpler. Therefore, FCoTR aims to resurrect Token Ring and make it the new dominant networking technology. Sounds simple and logical, right?

The amount of work put into this hoax is impressive.

  • There is an industry trade group, the Fibre Channel over Token Ring Alliance. In a nice touch, all of the links on the site are broken including the press release announcing its formation.
  • There is a FCoTR User Group, complete with twitter account.
  • The obligatory Wikipedia page is sadly already flagged for deletion.
  • There is a White Paper which was clearly created by a Markov chainer seeded with computer science and storage terminology, possibly SCIgen.
  • Dozens of tweets carry the hashtag #FCoTR.
  • Stephen Foskett wrote a long blog post about the idea. It starts off subtle, but becomes increasingly outrageous. As many people will only skim the first paragraph, they won't notice the claims at the end: Intel building a Micro Channel to PCI Express bridge to ease the introduction of token ring products, and Proteon making a comeback.

Greg Ferro has an excellent writeup about FCoTR and its motivations. In order to make a large network appear to be completely lossless, Fibre Channel has always relied on extremely complex designs. This leads to very expensive gear. Fibre Channel networks also run at relatively low utilization, because full buffers lead to packet loss. FC over Ethernet disrupts all of that. For vendors and storage mavens who feel threatened by a converged network, the solution is to push for a solution which will once again let them run a separate, single purpose, and thoroughly overengineered network. Token Ring meets these requirements.

Friday, July 16, 2010

Alternate Phone B

iPhone 4

Image courtesy of Apple

When Gizmodo acquired an iPhone 4 prototype, I recall a mention that Apple execs were especially annoyed because there had been two versions of the iPhone 4. The one Gizmodo recovered was the more aggressive of the two designs, with the other version prepared as a backup. When Gizmodo showed the prototype to the world, it became impossible to go with the alternate design.

When developing a backup release for any product, software or hardware, you want to minimize the resources spent on it. You spend most of the effort on the primary design, the more aggressive version. The primary will ship, its just a question of when, so the resources spent on it will not go to waste. The backup, in contrast, will ideally never see the light of day. You'd prefer to only spend resources on it which can also benefit the primary effort, and minimize the amount of throw-away work.

So what might the "Alternate Plan B" version of the iPhone 4 have been? Using the A4 CPU seems assured, as not using it would have led to uncomfortable questions. It presumably would also have incorporated the current versions of the baseband radio circuitry, and possibly the new gyroscope as well. If the gyro didn't work out, it could be marked no-stuff in assembly and the software support disabled. I'd speculate that the Alternate Plan B for iPhone 4 was a new board with A4 CPU and gyro sized to fit in a minimally modified 3GS housing.

I wonder which version would Apple have gone with, had they a choice?

Thursday, July 8, 2010

Virtual Instruction Sets: Opcode Arguments

Its a virtual CPU fan, get it?Virtual Machine architectures are a fascinating topic, and one that I plan to occasionally explore in this space. Not virtual machines in the sense of VMWare or Xen, rather the runtime environment for a programming language like Java or Python. This time we'll focus on the structure of the instruction set, in particular on how operands are passed and stored. Why are these low level details important?

  • Traditional compilers emit instruction sequences without knowing anything about the specific CPU model, system configuration, or input data to be processed.
  • The compiler can optimize for a specific CPU pipeline, and maybe even produce multiple binaries for different CPUs. As a practical matter you cannot produce a large number of variations due to the sheer size of the final binary image.
  • Profile-driven compilation can optimize for representative data you supply during the build phase, but representative data is always a guess and a compromise. Also as a practical matter, its difficult to use profile-driven optimization for many applications, such as GUIs.
  • Only a JIT for a virtual machine has the luxury of knowing the specific CPU, system configuration, and has profiling information from the current input data.

The hardware CPU architectures we use now have evolved in lockstep with compiler technology, and mostly C/C++ compilers at that. They have enormous I$ and D$ because the compiler cannot predict very much about what it will execute next. The hardware has extensive branch prediction logic and history tracking because compilers emit an average of one branch every 7 instructions.

Virtual Machines change everything: by profiling the running code they can produce instructions for this specific workload, resulting in long sequences of very predictable opcodes without branches or conditionals. It has the potential to change hardware architectures, once we pass a tipping point where most of the workload runs within a VM. I suspect this tipping point will be reached in mobile devices well before it impacts workstations, laptops, or servers.

This rosy prediction is by no means certain. The JIT for most current VMs will compile a function the first time it is used. They can optimize for the CPU and possibly even take memory size into account, but they don't use any profiling information. Thus the JIT can potentially get the benefit of compiling for the specific CPU pipeline on which it runs, though in practice even this isn't typically done. So far as I know of the VMs discussed here only Mozilla's Spidermonkey makes use of tracing to produce specifically optimized routines according to the input data being processed.

We're going to examine seven virtual machines, focussing on how operands are passed: the JVM, CLR, Spidermonkey, LLVM, Parrot, V8, and Dalvik.


JVM & CLR

JVM argument stackThe Java Virtual Machine and the Common Language Runtime used by .Net are certainly very different, but as virtual machines go they have a lot in common. Both are stack based: operands to an instruction are popped from the stack, and the result is pushed.

Stack based virtual machines are relatively common, because they are conceptually very simple. Indeed many early microprocessors and microcontollers were stack based, because the silicon technology of the day wouldn't allow a CPU with a generous number of registers on the die. In that sense virtual CPUs are following the same evolutionary path as hardware CPUs did several decades ago, starting with stack based machines and adding registers later.

Stack-based instruction sets tend to have a very high code density, because their opcodes don't need to encode source and destination register numbers. When the JVM was developed in the early 1990s, processor caches were measured in the tens of kilobytes. A densely packed bytecode was a big advantage, far more bytecode could be stored in the hardware CPU's data cache.


Spidermonkey (Firefox)

SpiderMonkey is the Javascript engine in Firefox, and is a stack-based machine like the JVM and CLR. What I find most interesting about SpiderMonkey is that it tackled profile-driven JIT optimization first, via TraceMonkey in the latter part of 2008. A more conventional method-compiling JIT came later, via JaegerMonkey in early 2010. The virtue of doing things in this order is pretty compelling: tracing, when it works, can deliver spectacular gains. However tracing really only helps with loops, leaving lots of low hanging fruit for a method-based JIT. Doing the method-based JIT first makes it more difficult to get the profiling information which tracing needs. By doing TraceMonkey first, its instrumentation needs became part of the requirements for JaegerMonkey.


LLVM

The primary design point of the LLVM project is a compiler toolchain, and the LLVM instruction set was designed to be the intermediate representation between the language-specific frontend and more generic backend. The LLVM instruction set defines a register based virtual machine with an interesting twist: it has an infinite number of registers. In keeping with its design point as a compiler intermediate representation, LLVM registers enable static single assignment form. A register is used for exactly one value and never reassigned, making it easy for subsequent processing to determine whether values are live or can be eliminated.


Parrot

Parrot is also a register based virtual machine. It defines four types of registers:

  1. Integers
  2. Numbers (i.e. floating point)
  3. Strings
  4. Polymorphic Containers (PMCs), which reference complex types and structures

Like LLVM, Parrot does not define a maximum number of registers: each function uses as many registers as it needs. Functions do not re-use registers for different purposes by storing their values to memory, they specify a new register number instead. The Parrot runtime will handle assignment of virtual machine registers to CPU registers.

So far as I can tell, integer registers are the width of the host CPU on which the VM is running. A Parrot bytecode might find itself using either 32 or 64 bit integer registers, determined at runtime and not compile time. This is fascinating if correct, though it seems like BigNum handling would be somewhat complicated by this.


V8 (Chrome)

V8 is the JavaScript engine in the Chrome browser from Google. Its a bit of a misnomer to call V8 a virtual machine: it compiles the Javascript source for a method directly to machine code the first time it is executed. There is no intermediate bytecode, and no interpreter. This is an interesting design choice, but for the purposes of this article there isn't much to say about V8.


Dalvik (Android)

Dalvik virtual machine registersDalvik is the virtual machine for Android application code. The Dalvik instruction set implements an interesting compromise: it is register based, but there are a finite number of them as opposed to the theoretically infinite registers of LLVM or Parrot. Dalvik supports 65,536 registers, a vast number compared to hardware CPUs and presumably sufficient to implement SSA (if desired) in reasonably large functions.

Even more interestingly, not all Dalvik instructions can access all registers. Many Dalvik instructions dedicate 4 bits to the register number, requiring their operands to be stored in the first 16 registers. A few more instructions have an 8 bit instruction number, to access the first 256. There are also instructions to copy the value to or from any of the 65,536 registers to a low register, for a subsequent instruction to access.

It took a while to understand the rationale for this choice, and I'm still not confident I fully get it. Clearly the Dalvik designers believe that keeping data in one of the high registers will be faster than explicitly storing it to memory, even if the vast number of registers end up mostly residing in RAM. Addressing data as register numbers instead of memory addresses should make it easier for the VM to dynamically remap Dalvik registers to the real hardware registers. For example, if it can predict that virtual register 257 will likely be used in the near future it can be kept in a CPU register instead of being immediately stored to memory.


Other VMs

There are many, many more virtual machine implementations beyond the ones implemented here. The Python, Smalltalk, and Lua programming languages each have their own VM instruction set and implementation. Erlang started with a VM called JAM, and later reimplemented the underpinnings in a new virtual machine called BEAM. Adobe Flash has a VM which has been open sourced and donated to the Mozilla project as Tamarin. Wikipedia lists brief descriptions of a number of current VMs.

Tuesday, July 6, 2010

The New Intelligence Agency: All of Us

Yesterday Louis Gray pieced together vague snippets of information from tweets made by the founders and investors of Foursquare and Brizzly to speculate that Foursquare was negotiating to buy Brizzly. Later that day the speculation was denied by all parties involved. To (loosely) quote Mandy Rice-Davies: "They would deny it, wouldn't they?"   ... I don't think this story is over.

Nonetheless the details of the speculated transaction are not our topic today. Instead, I'd like to consider the process which led to it. For decades government (and sometimes corporate) intelligence operations have had access to reams of communications data from which to make inferences. They could see who was calling whom, where letters and packages were being delivered, and know people's movements to some extent via airline manifests. Intelligence agencies are famous for collecting massive amounts of information and using algorithms to look for patterns, to be followed up by a human analyst.

We're rapidly moving into a world where a significant amount of that information is available to anyone who cares to look for it. We're using social networks which broadcast our updates publicly, either deliberately or because we don't understand the privacy settings. We're rapidly integrating location data into online applications, which people willingly share if they see a benefit from it. As the tweets Louis quoted show, people also love making coy hints about their dealings, secure in the knowledge that nobody will figure out such a vague hint. Yet given enough vague data, particularly if one is aware of existing connections between the participants, correlations can be found. Certainly there will be false positives, but there will also be some real gems.

Systematic data mining of social networks, both their contents and the metadata they contain, in order to gain competitive advantage has enormous implications. It apparently is already happening: military raids have been cancelled due to leaks on social networks, showing that government agencies are concerned about the possibility. For the most part it won't be reported on, and will become just another part of the Internet underpinnings.

Thursday, July 1, 2010

Voyager 2 Soft Error

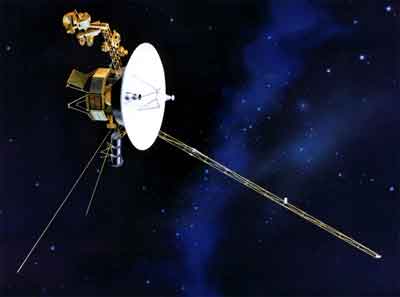
Voyager 2Voyager 2 is currently traversing the heliosphere, the shockwave where the solar wind and particles of the interstellar medium meet. Decades after launch the Voyager probes are still transmitting data back to Earth, at 160 bits per second. Starting April 22, 2010, the checksums in the Voyager 2 datastream indicated problems in every frame. Something bad had happened to the spacecraft.

After several weeks of testing, JPL determined the root cause to be a flipped bit in the computer's memory. A bit had spontaneously changed from zero to one. JPL duplicated the incorrect checksum symptom by deliberately flipping that bit on a terrestrial copy of the Voyager computer system. On May 19, 2010 a command was sent to reset the bit to zero, and the next day (after 13 hour propagation delay each way) Voyager 2's datastream returned to normal.

It appears to have been a soft error. What is most interesting about this is the technology involved: the Voyager computer systems use magnetic core memory. On Earth, soft errors in core memory of this vintage are essentially impossible. The amount of energy required to flip the bit is so large that any particle with sufficient charge would have been deflected by the Earth's magnetic field. Out at the heliosphere, particles carrying sufficient energy to affect the core memory are apparently present.

Software engineers at JPL are currently working on a software patch to stop using that bit in the core. It is possible that the problem wasn't purely random, that instead this particular bit of hardware is degrading and no longer holding its state reliably.

Monday, June 28, 2010

Toxoplasmowhosit?

ToxoplasmosisToxoplasmosis has long been known to modify the behavior of its host mice, influencing them in ways which make it more likely they will be eaten by a cat. The microbe reproduces in the intestines of felines. The chemicals it produces to effect this appear to also have an impact in other mammals, including humans. As cats do not normally eat humans, effects on humans are just an accident.

Natural selection will eventually produce a toxoplasmosis microbe which forces humans to take felines into their homes and care for them, producing a much larger population of suitable environments for their reproduction. When this happens, when large numbers of humans willingly share their homes with cats, then we will know that the microbes have taken over.

Thursday, June 24, 2010

Virtual Trouble

After many years of working in plain C, I'm back to writing C++. I feel like an unfrozen caveman, confused by the flashing lights of the big city. Here is something I ran into recently.

#include <stdio.h>

class BaseClass {
 public:
  BaseClass() { InitName(); }
  virtual void InitName() { name_ = "BaseClass"; }
  char *name_;
};

class SubClass : public BaseClass {
 public:
  virtual void InitName() { name_ = "SubClass"; }
};

int main(int argc, char** argv) {
  BaseClass base;
  SubClass sub;

  printf("BaseClass name_ = %s\n", base.name_);
  printf("SubClass  name_ = %s\n", sub.name_);
}

A base class provides a virtual InitName() method, and calls it from the constructor. A subclass overrides InitName(), yet the overridden method is not called during construction. The BaseClass InitName() is used instead.

$ ./a.out
BaseClass name_ = BaseClass
SubClass  name_ = BaseClass

Why?


A Maze of Twisty Little Passages

Objects are constructed from the most basic class first. When the BaseClass() constructor runs, the SubClass methods and member variables have not yet been initialized. The object is a BaseClass object at that point. When BaseClass::BaseClass() returns, the object will be remarked as a SubClass object, and only then will its overridden methods actually do anything. Destructors work similarly. The outermost derived class is destroyed first, and by the time BaseClass::~BaseClass() runs the object will be of BaseClass type. Any virtual methods called from ~BaseClass() will call the BaseClass definition.

Scott Meyers Effective C++, Third Edition

Scott Meyers' Effective C++, 3rd Edition devotes a chapter to this topic, with considerably more detail. That chapter happens to be available online in an excerpt by the publisher.

For my specific issue, my object already had an Init() method to be called after object construction. It was straightforward to move the functionality from the constructor to Init(), with some checks to make it do something sensible if the caller neglects to call Init().

Monday, June 21, 2010

Stackoverflow Maintenance Page

I love how the stackoverflow.com maintenance page show a binary dump of a Windows process where the stack overflow error is defined. Clever.

Stackoverflow is down for maintenance.

Thursday, June 17, 2010

A Moon of Endor

At the time of this writing 455 planets outside of Earth's own solar system have been discovered. Nearly all are gas giants like Jupiter and Saturn, and even the smallest are several times the mass of Earth. This doesn't mean smaller planets are uncommon, it means our current techniques using optical occlusion and gravitational deflection are far better at detecting massive planets.

When I read reports on these discoveries they have already been "dumbed down" for a mainstream audience. Invariably the lack of Earth-like planets is mentioned, followed by a reference to extraterrestrial life on those Earth-like planets. Yet I suspect that if we're really interested in finding planets where life is likely to have evolved, gas giants are what we should be looking for.

Mars as seen by the Hubble space telescope.In our own solar system there are three "Earth like" planets: Venus, Earth, and Mars. Of the three, only Earth is tectonically active with a strong magnetic field. Tectonics and vulcanism leads to temperature variation in the environment, which on Earth appears to spur evolution. A strong magnetic field protects the planet's surface from solar flares.

Something about Earth is different, resulting in it having a highly dynamic molten core where Mars and Venus are far more settled. One possibility is the Moon: Earth has a relatively enormous moon compared to Mars. The force of lunar gravity exerts considerable strain on the planet, and perhaps that keeps the inner dynamo from settling. Another possibility is related to the formation of the moon: if indeed it formed due to a massive asteroid strike on the Earth ejecting a huge volume of material into space, then perhaps the planet simply hasn't settled down yet.

The moons of a gas giant have some of the same properties as Earth. The massive gravity of their neighbor exerts considerable force, making a dynamic molten core more likely. If their orbit is close enough they also sit inside their host's magnetic field, protecting them from solar wind and flares. There is a considerable amount of radiation near a gas giant, but its a constant level which becomes part of the environment. On Earth life seems able to evolve in extremely harsh environments, so perhaps life can evolve on a gas giant moon in spite of the radiation. In our own solar system it is possible that life exists on Titan, which would be incredibly exciting.

Advancements in our ability to detect Earth-like exoplanets is interesting, but to me it will be far more interesting when we can detect moons orbiting gas giants.